DeepSeek V4.1 Flash
DeepSeek's smaller V4.1 model: 552B parameters, 8B active on input and 16B on output, a 1M context, vision in and text out. Open weights.
Open DeepSeek V4.1 Flash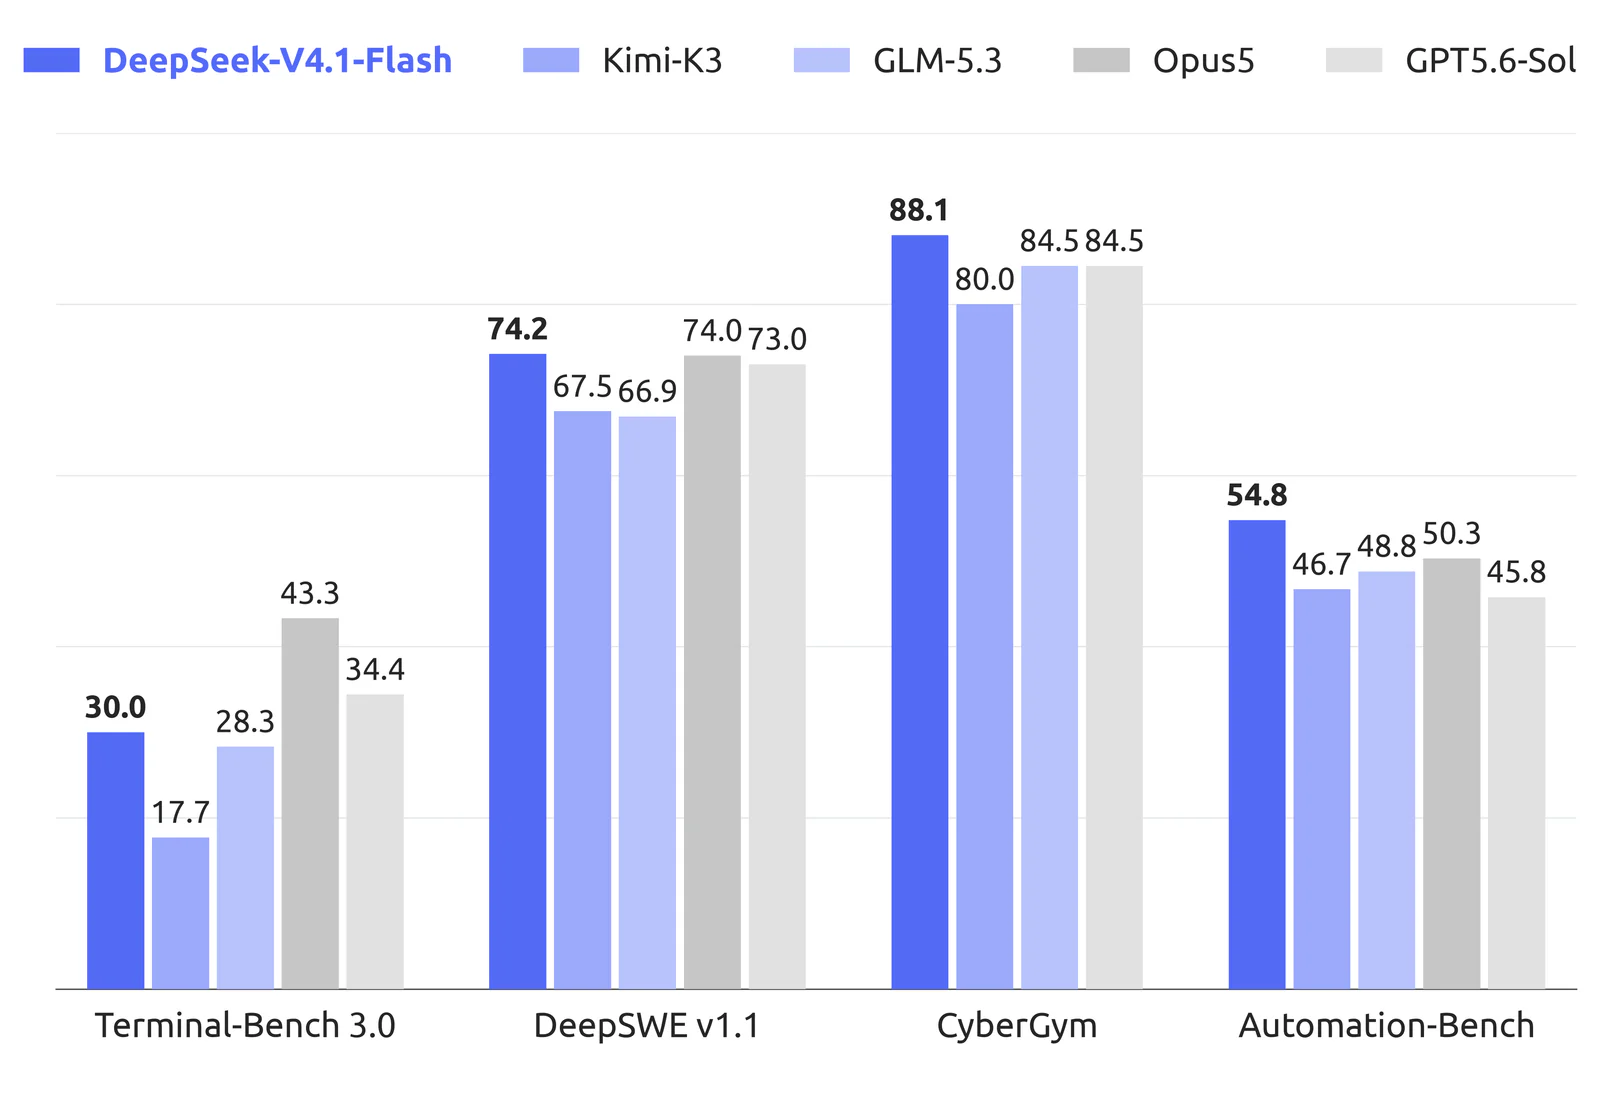
deepseek/deepseek-v4.1-flash is DeepSeek V4.1 Flash, the smaller model in the V4.1 family. DeepSeek describes a 552B-parameter mixture of experts with a causal encoder-decoder: 8B parameters active while it reads, 16B while it writes. It takes text and images, answers in text, and the context window is 1,048,576 tokens. Reasoning effort is controllable. The weights are on Hugging Face under MIT. The release note and the tech report are DeepSeek's.
DeepSeek's own agentic chart puts V4.1 Flash at 30.0 on Terminal-Bench 3.0, 74.2 on DeepSWE v1.1, 88.1 on CyberGym, and 54.8 on Automation-Bench. Those bars are the vendor's comparison with Kimi-K3, GLM-5.3, Opus 5, and GPT-5.6 Sol.
Epoch AI scores in our catalog, separate from that chart: GPQA Diamond 89.8, OTIS Mock AIME 98.3, ARC-AGI-2 72.9, SciCode 51.9, SimpleQA Verified 42.9.
| Benchmark | Score | Source |
|---|---|---|
| Terminal-Bench 3.0 | 30.0 | DeepSeek |
| DeepSWE v1.1 | 74.2 | DeepSeek |
| CyberGym | 88.1 | DeepSeek |
| Automation-Bench | 54.8 | DeepSeek |
| GPQA Diamond | 89.8 | Epoch AI |
| OTIS Mock AIME | 98.3 | Epoch AI |
| ARC-AGI-2 | 72.9 | Epoch AI |
| SciCode | 51.9 | Epoch AI |
| SimpleQA Verified | 42.9 | Epoch AI |
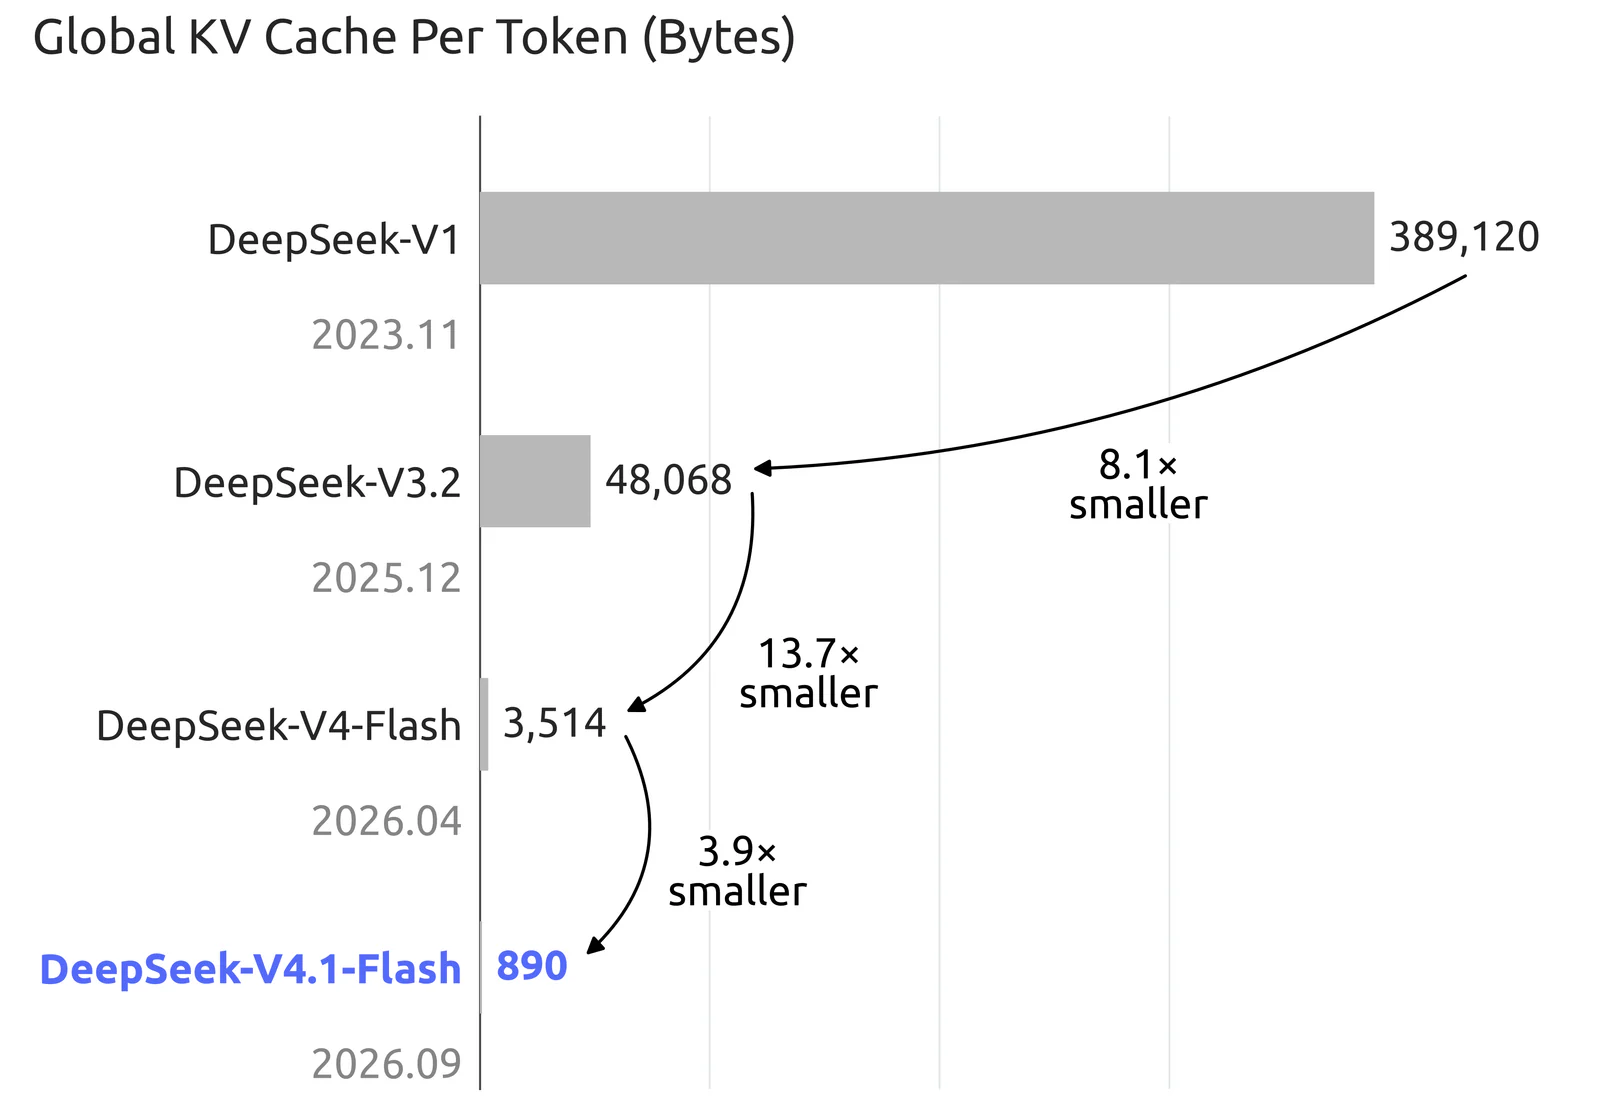
The same card shows the KV cache shrinking across DeepSeek generations. DeepSeek says V4.1 Flash needs about a quarter of the previous generation's HBM for that cache, and about an eighth of the SSD. Cache-hit cost is a large share of a long agent run, so a smaller cache is the point of the architecture.
- App code: Vercel AI SDK or OpenAI SDK.
- Coding agent:
anyr claude/anyr opencode/anyr codex(playground). - Bring your own key: Dashboard → BYOK.
Call it with your own key. AnyRouter adds no per-token charge on that path. Try it with the Vercel AI SDK; createAnyRouter() reads ANYROUTER_API_KEY:
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"

const anyrouter = createAnyRouter()

const { text } = await generateText({
  model: anyrouter("deepseek/deepseek-v4.1-flash"),
  prompt: "Rank these three refactors by risk and say why.",
})
console.log(text)
Or launch a coding agent through the anyr CLI:
curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr claude --model "deepseek/deepseek-v4.1-flash"
curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr opencode --model "deepseek/deepseek-v4.1-flash"curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr codex --model "deepseek/deepseek-v4.1-flash"More: AI SDK · OpenAI SDK · coding agents · BYOK setup.
Related posts
- Use AnyRouter in DeepSeek HarnessGuidesNovember 2, 2026 · DeepSeek Harness is DeepSeek's open-source agent app, now in preview. Add AnyRouter as a custom model API with one base URL and one key, then pick an anyrouter/* router model for each kind of work.
- Qwen3.8-27B and DeepSeek V4 Flash, 50% offProductAugust 20, 2026 · Half off through 1 Sep. Same API, same model ids, just a friendlier bill.
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.