Sarvam 105B 1711
Sarvam's 105B MoE flagship joins the catalog on the new 1711 weights: 10.3B active parameters, a 128K context, tool calling and Indian-language support. BYOK only.
Open Sarvam 105B
sarvam/sarvam-105b runs Sarvam's 1711 weights. It is a 105B-parameter sparse mixture-of-experts model with 10.3B active parameters and multi-head latent attention, built for reasoning, agentic tool use and the ten most-spoken Indian languages.
The API exposes a 128K context window. Reasoning is on by default and reasoning tokens count toward max_tokens; set reasoning_effort to none to turn it off. Open weights are Apache 2.0 in NVFP4 and BF16.
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"
const anyrouter = createAnyRouter()
const { text } = await generateText({ model: anyrouter("sarvam/sarvam-105b"), prompt: "Hello" })curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
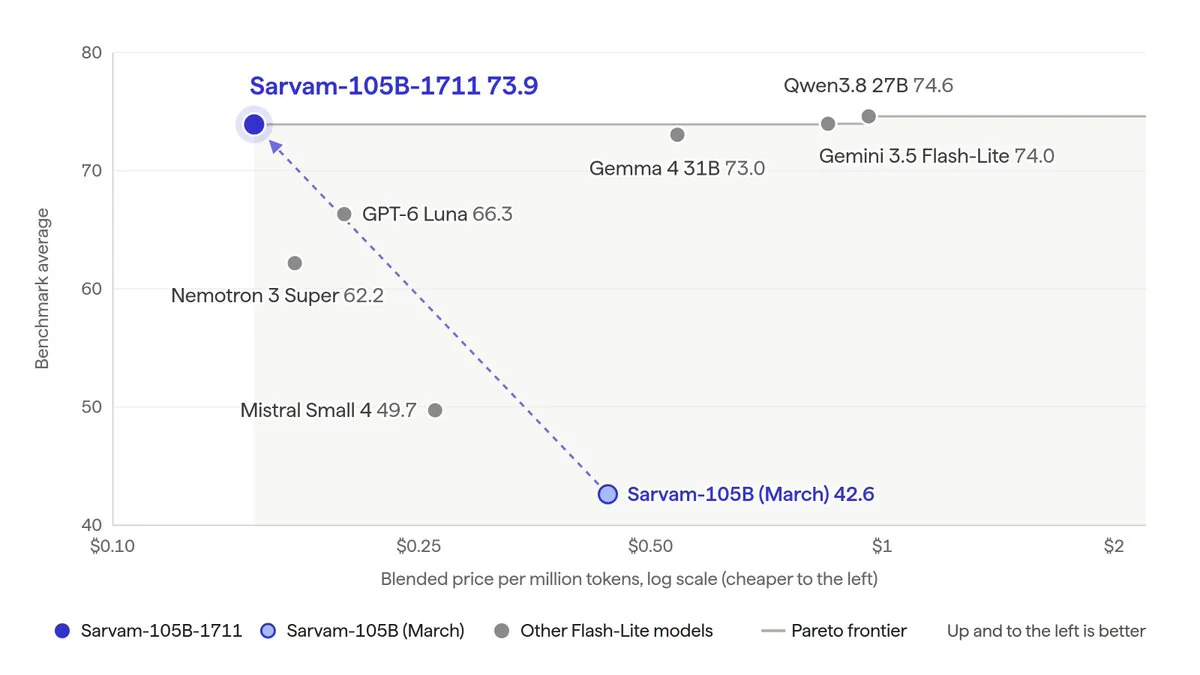
anyr claude --model "sarvam/sarvam-105b"It is BYOK-only. Add your own Sarvam key under Dashboard → BYOK. AnyRouter does not charge credits for the hop. Read the model card for the full benchmark table.
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.