All releasesTất cả bản phát hành全部发布
AddedĐã thêm新增
Nemotron 3.5 Bolt E4B
NVIDIA's Nemotron 3.5 Bolt E4B joins the catalog: a small, fast model post-trained from Gemma 4 E4B for tool use and voice assistants.
Open Nemotron 3.5 Bolt E4B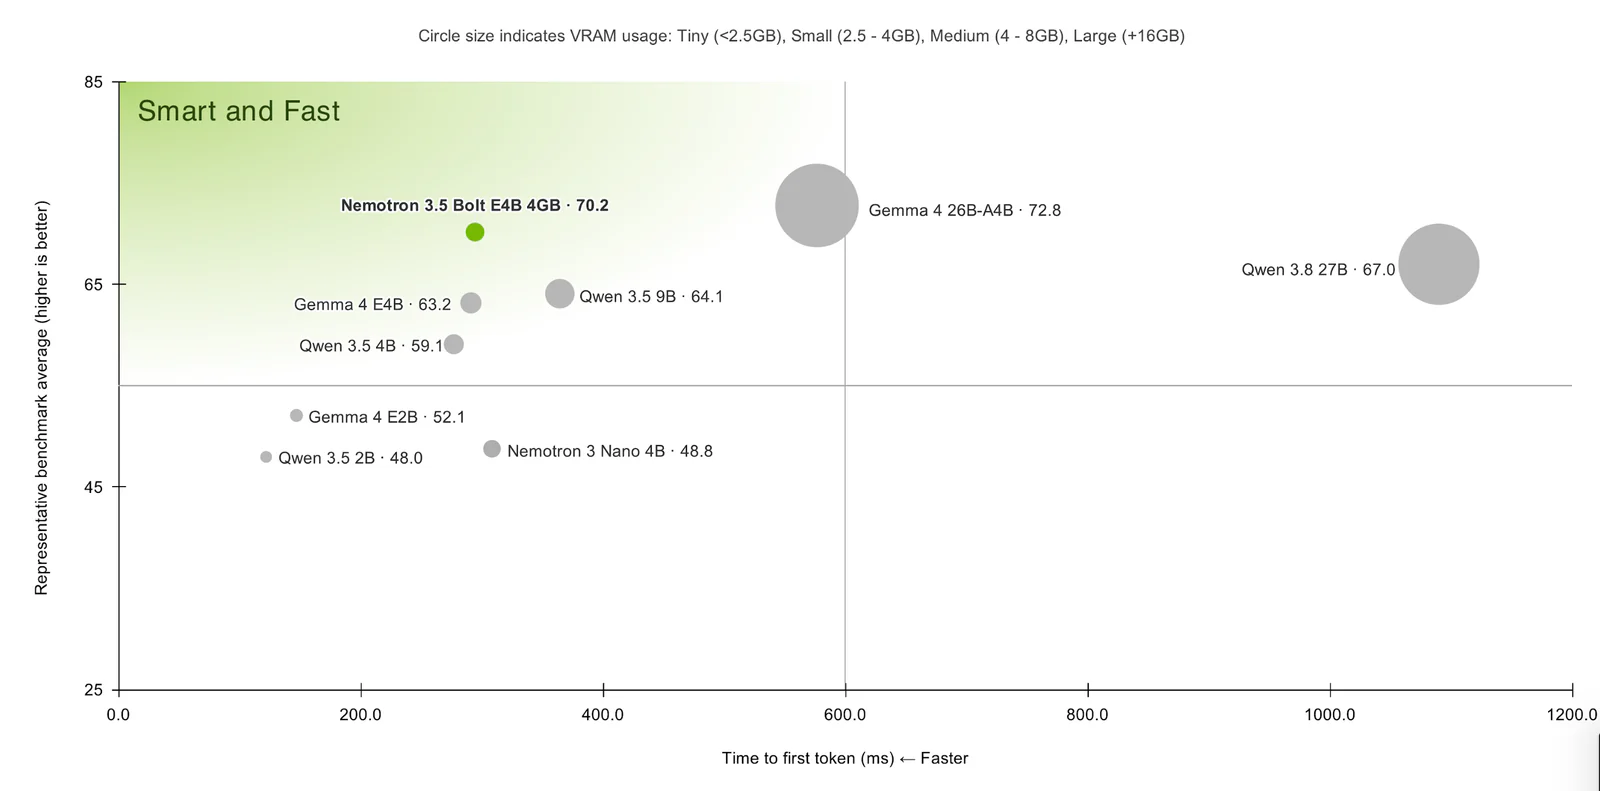
nvidia/nemotron-3.5-bolt-e4b is a small language model NVIDIA post-trained from Gemma 4 E4B (8B parameters, 4B effective). NVIDIA reports better multi-turn tool use, instruction following and input grounding than Gemma 4 E4B, with low memory use and low time to first token. Context is 64K tokens. It is a good fit for voice and device assistants, interactive personas and embedded interfaces. Weights are open under OpenMDW-1.1.
AI SDK
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"

const anyrouter = createAnyRouter()
const { text } = await generateText({
  model: anyrouter("nvidia/nemotron-3.5-bolt-e4b:free"),
  prompt: "Reply in one sentence: what can you help me with?",
})
console.log(text)
Coding agent
curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr claude --model "nvidia/nemotron-3.5-bolt-e4b:free"
Playbooks: AI SDK, coding agents, OpenAI SDK.
Related posts
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.