MiniMax M3.1 Flash
MiniMax's multimodal agent and coding model joins the catalog, free on NVIDIA's developer tier.
Open MiniMax M3.1 Flash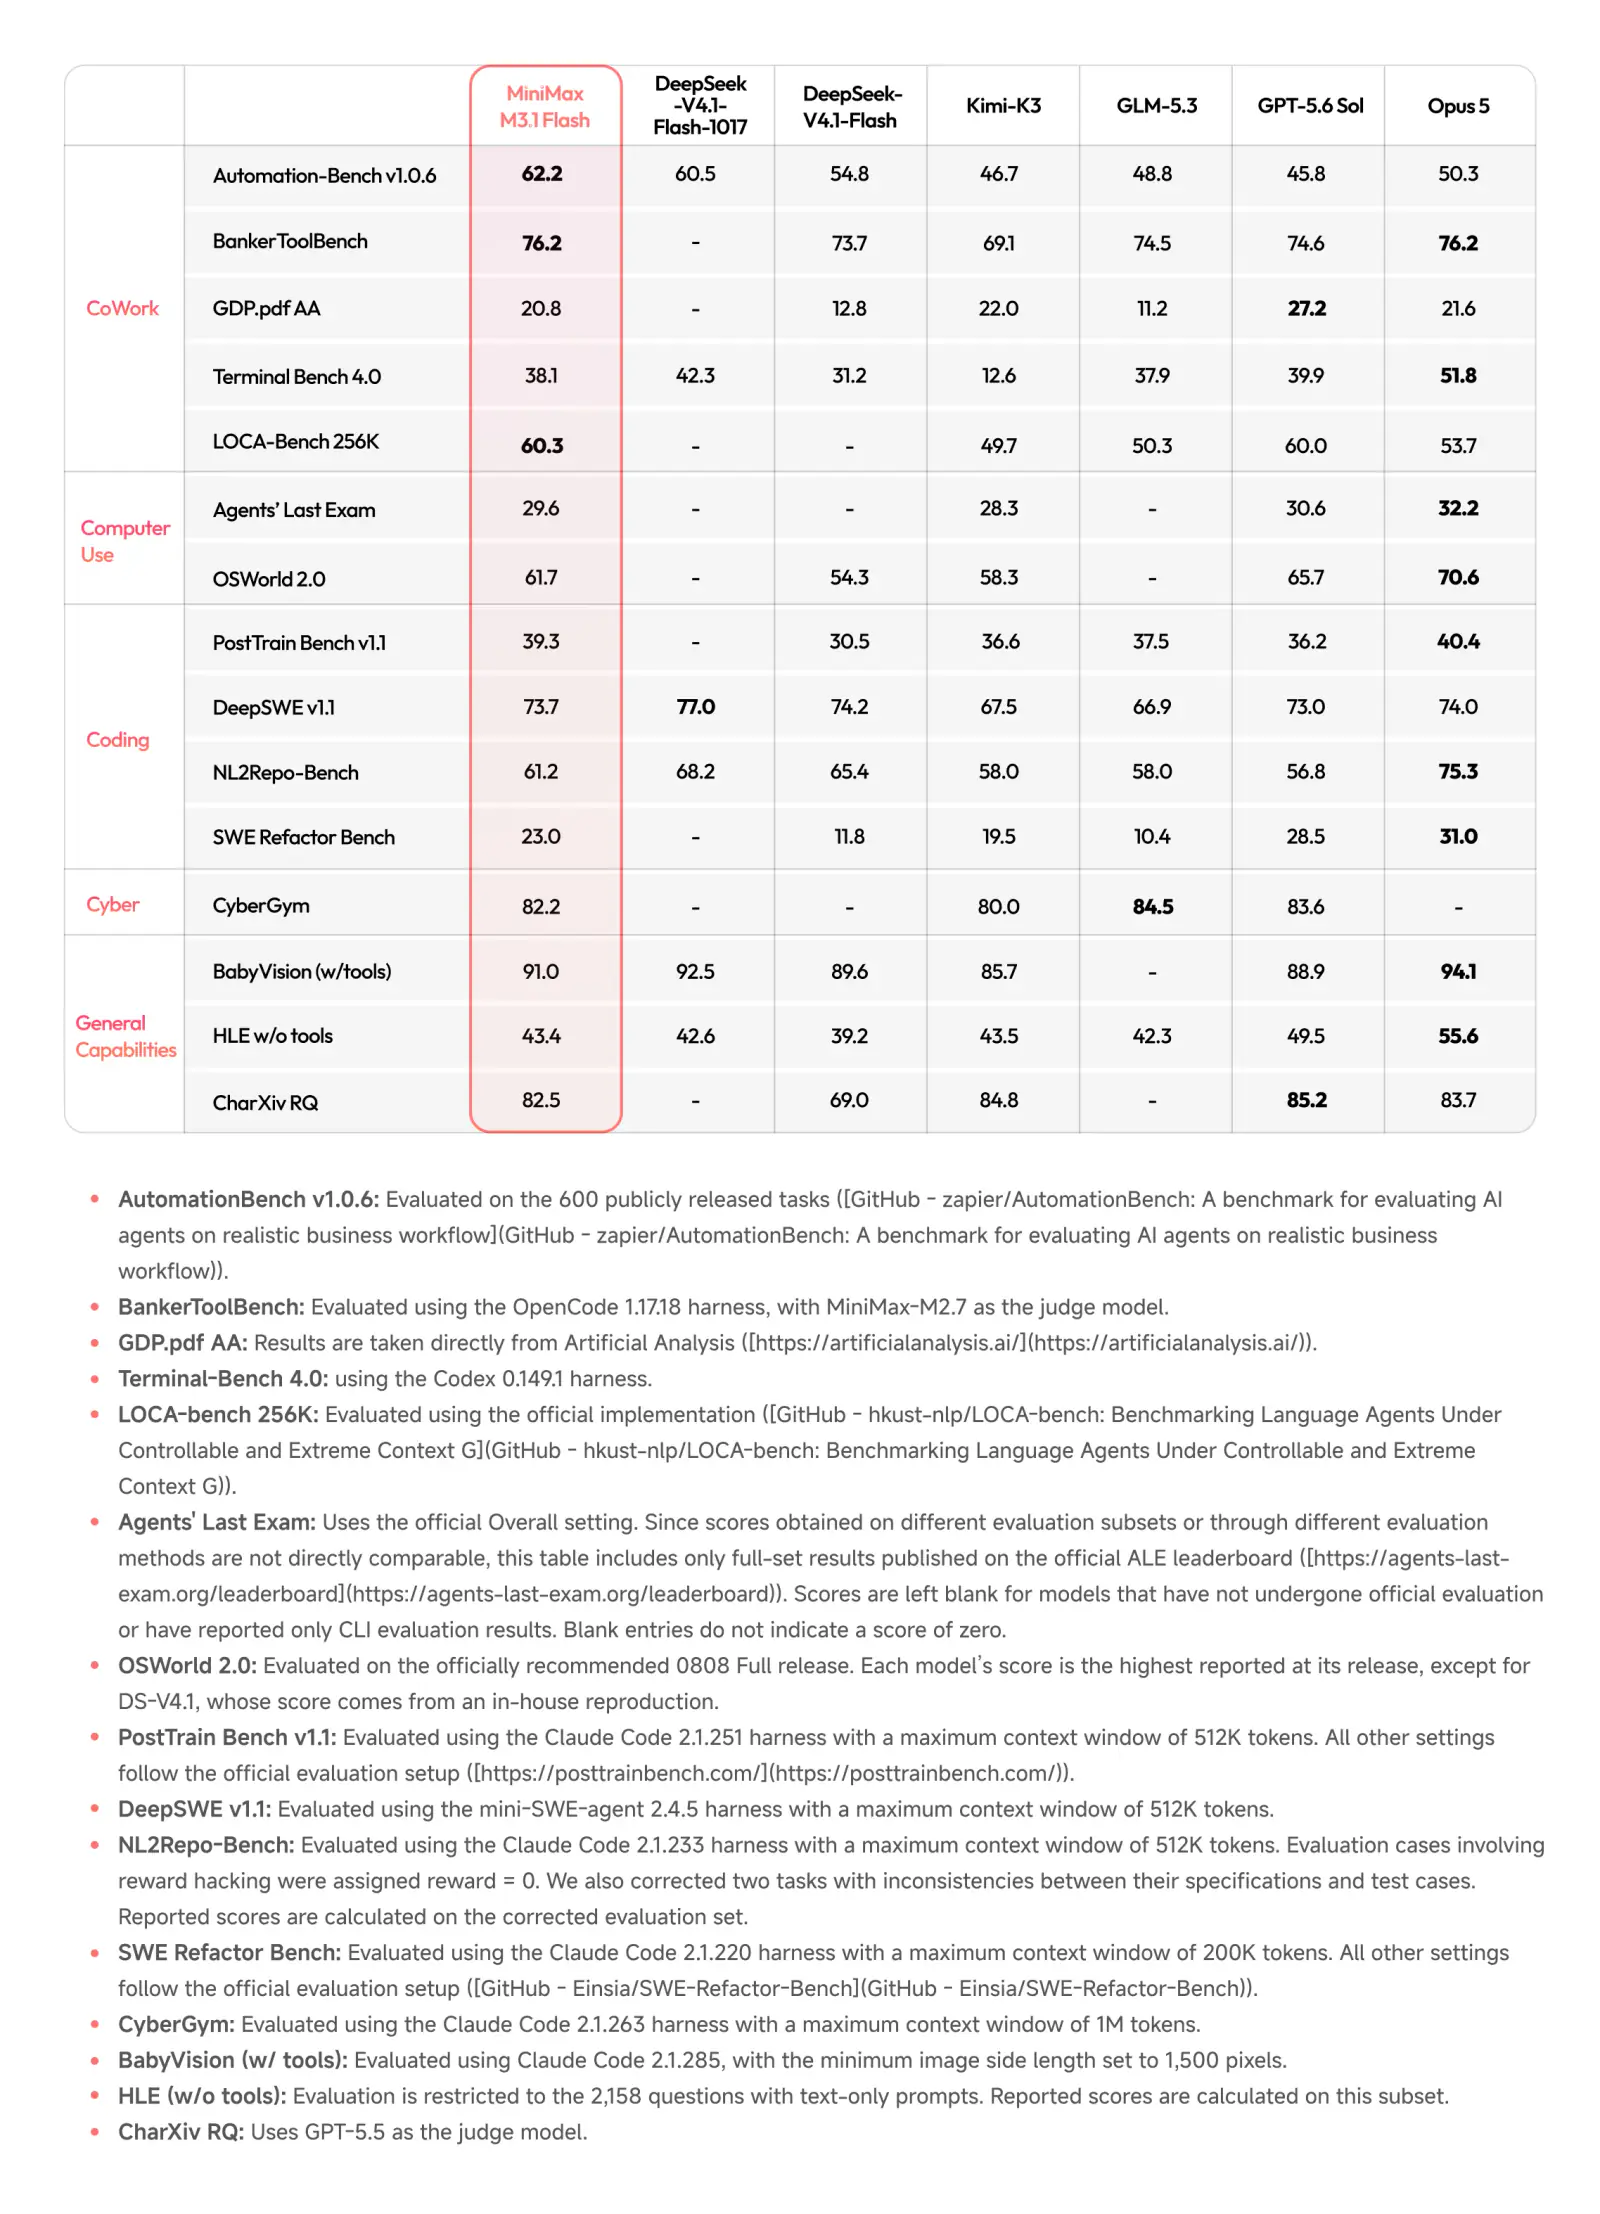
Update 2026-10-25: the launch-week free offer has ended (OpenRouter, Kilo, Cline and OpenCode Go retired their free ids on 2026-10-22). It is free again through NVIDIA's own free endpoint, which is rate limited and has no published price. Call minimax/minimax-m3.1-flash:free with your AnyRouter key to use it. Every other route is paid, so add your own MiniMax, OpenRouter or Vercel key for steady use.
MiniMax M3.1 Flash is built for agent work and coding. It has a 1M token context, takes text, image and video, and always reasons. List price is $0.15 input and $0.60 output per 1M tokens. With your own MiniMax key under Dashboard → BYOK, you pay MiniMax directly at that price.
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"
const anyrouter = createAnyRouter()
const { text } = await generateText({ model: anyrouter("minimax/minimax-m3.1-flash:free"), prompt: "Find the bug in this function." })curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr claude --model "minimax/minimax-m3.1-flash:free"Playbooks: AI SDK, coding agents, OpenAI SDK.
Related posts
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.