GLM-5.3-Flash: Ox Alpha, named
The Ox Alpha preview is GLM-5.3-Flash: native multimodal, 1M context, MIT-licensed 320B-A18B. Same AnyRouter routes, catalog id z-ai/glm-5.3-flash.
Open GLM-5.3-Flash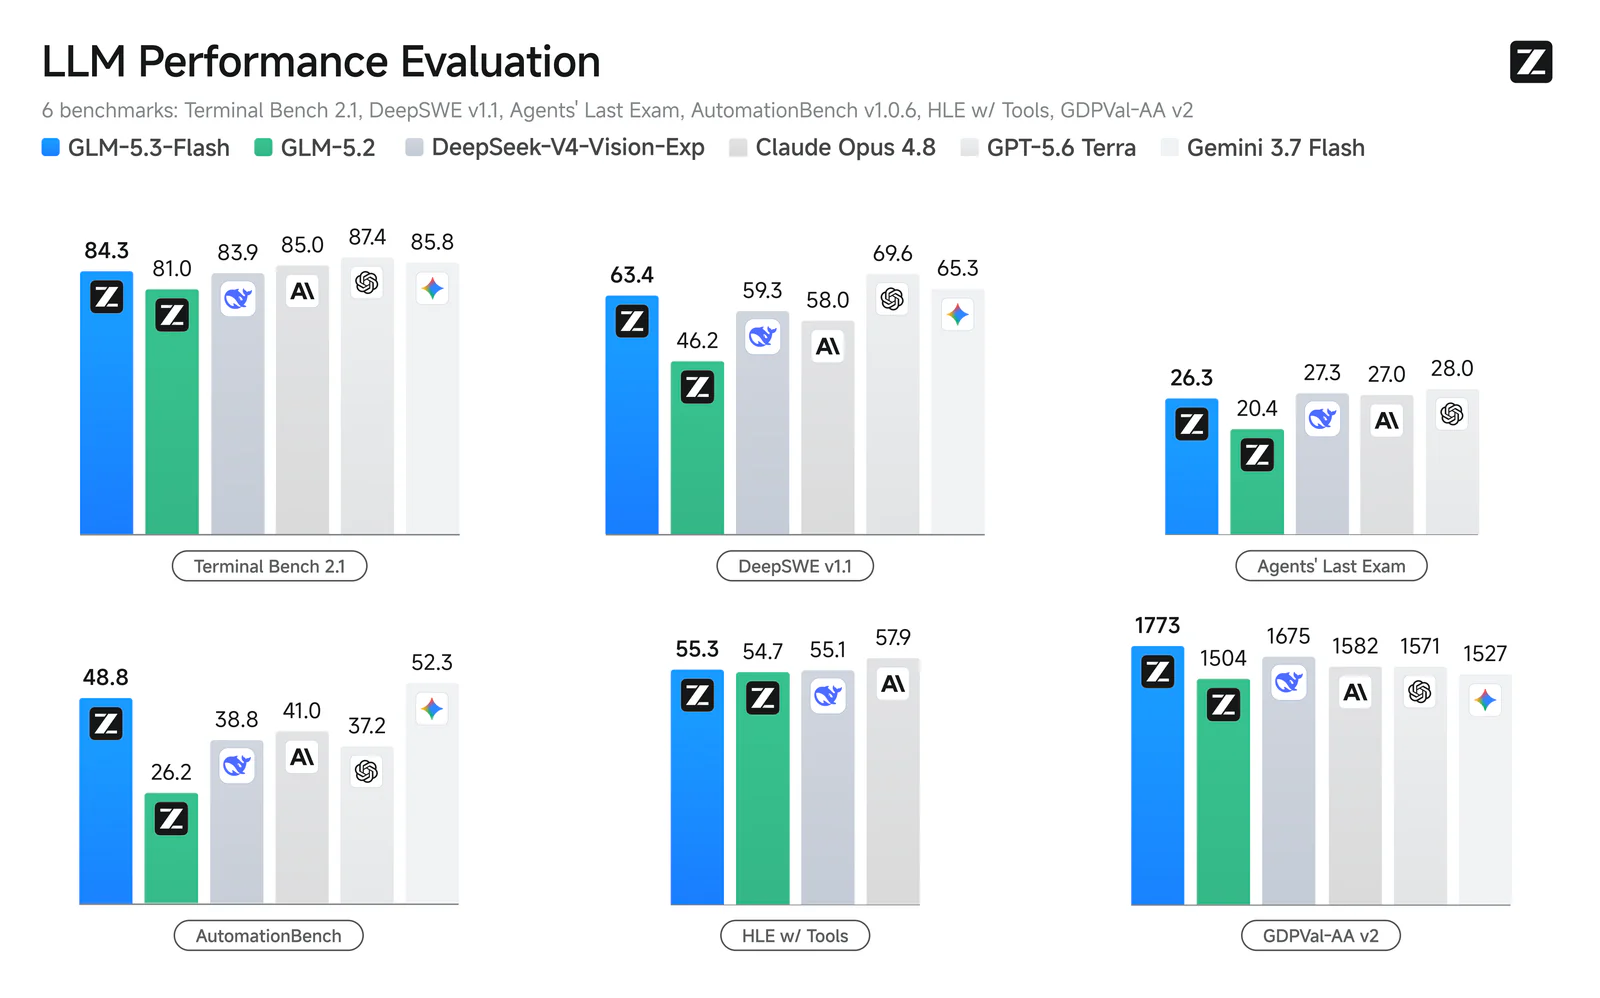
The model AnyRouter listed as stealth/ox-alpha is GLM-5.3-Flash. Same routes, new public name, official launch. Call z-ai/glm-5.3-flash. The old id stays for history, ranking, and leaderboard. It is unlisted from GET /api/v1/models and the /models picker.
GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture maintains accurate long-context behavior while reducing compute overhead. 320B-A18B, MIT License, 1M-token context. Z.ai ran the Ox Alpha preview entirely on Chinese AI chips.
Leading capabilities at a highly competitive price. Host routes keep the copied Ox Alpha $0/$0 rates. Z.ai's API docs list Coding Plan points, not a $/1M list we can copy. Announcement · weights · API.
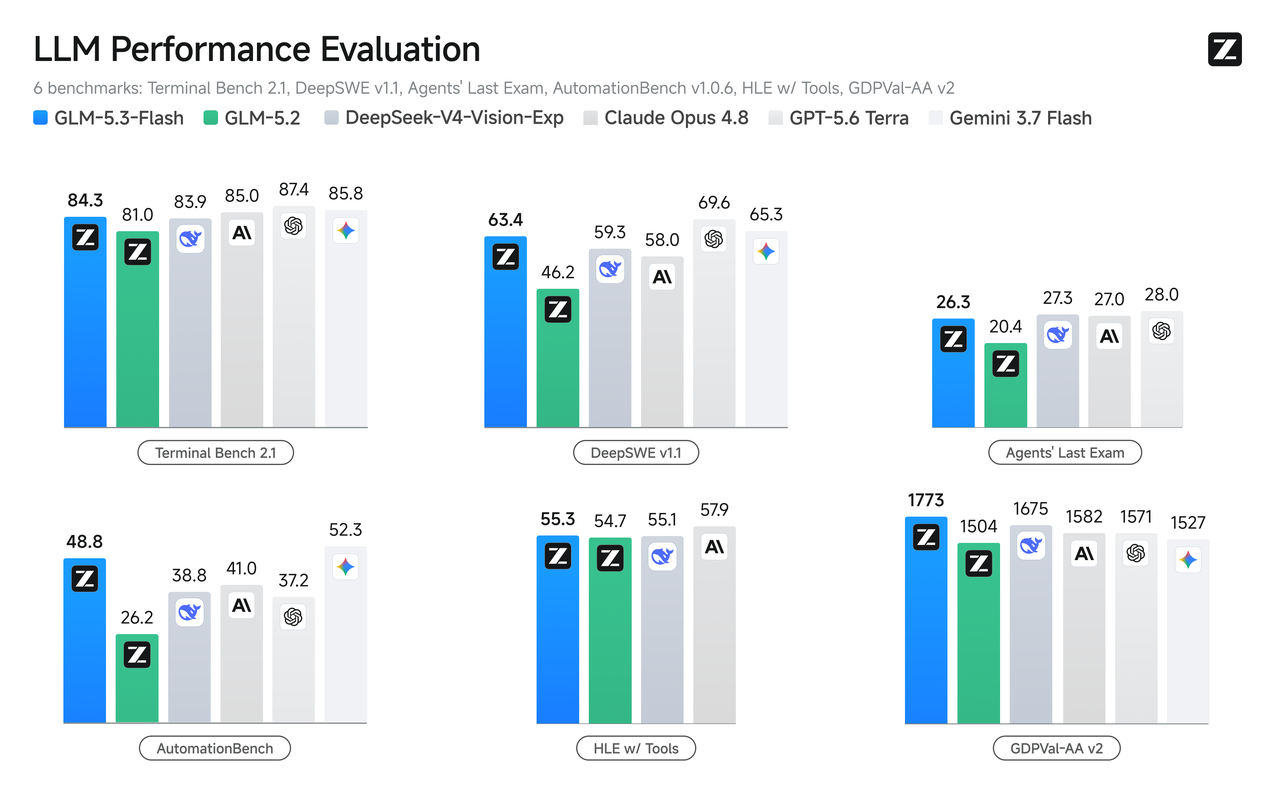
| Benchmark | GLM-5.3-Flash | GLM-5.2 | DeepSeek-V4-Vision-Exp | Claude Opus 4.8 | GPT-5.6 Terra | Gemini 3.7 Flash |
|---|---|---|---|---|---|---|
| Terminal Bench 2.1 | 84.3 | 81.0 | 83.9 | 85.0 | 87.4 | 85.8 |
| DeepSWE v1.1 | 63.4 | 46.2 | 59.3 | 58.0 | 69.6 | 65.3 |
| Agents' Last Exam | 26.3 | 20.4 | 27.3 | 27.0 | 28.0 | , |
| AutomationBench v1.0.6 | 48.8 | 26.2 | 38.8 | 41.0 | 37.2 | 52.3 |
| HLE w/ Tools | 55.3 | 54.7 | 55.1 | 57.9 | , | , |
| GDPVal-AA v2 | 1773 | 1504 | 1675 | 1582 | 1571 | 1527 |
DeepSWE v1.1: Flash vs GLM-5.2
Z.ai chart. GLM-5.3-Flash 63.4, GLM-5.2 46.2.
AutomationBench v1.0.6: Flash vs GLM-5.2
Z.ai chart. GLM-5.3-Flash 48.8, GLM-5.2 26.2.
- Announcement
- Weights (
zai-org/GLM-5.3-Flash) - API docs
- Coding Plan · ZCode · Chat · AutoClaw
- App code: Vercel AI SDK or OpenAI SDK.
- Coding agent:
anyr claude/anyr opencode/anyr codex(playbook). - No code: playground.
Try it in the Vercel AI SDK. createAnyRouter() reads ANYROUTER_API_KEY:
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"

const anyrouter = createAnyRouter()

const { text } = await generateText({
  model: anyrouter("z-ai/glm-5.3-flash"),
  prompt: "Summarize this diff in three bullets.",
})
console.log(text)
Already on the OpenAI SDK? OpenAI SDK playbook:
import OpenAI from "openai"

const client = new OpenAI({
  baseURL: "https://anyrouter.dev/api/v1",
  apiKey: process.env.ANYROUTER_API_KEY,
})

const res = await client.chat.completions.create({
  model: "z-ai/glm-5.3-flash",
  messages: [{ role: "user", content: "Hello" }],
})
console.log(res.choices[0]?.message.content)
curl https://anyrouter.dev/api/v1/chat/completions \
-H "Authorization: Bearer $ANYROUTER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"model":"z-ai/glm-5.3-flash","messages":[{"role":"user","content":"Hello"}]}'Or launch a coding agent through the anyr CLI:
curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr claude --model "z-ai/glm-5.3-flash"
curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr opencode --model "z-ai/glm-5.3-flash"curl -fsSL https://anyr.dev/cli.sh | bash
anyr login
anyr codex --model "z-ai/glm-5.3-flash"More: AI SDK · OpenAI SDK · coding agents.
No terminal? Open the playground and send a first message.
Try in playgroundRelated posts
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.