Inkling 2 Mini
Thinking Machines' small open-weights multimodal model joins the catalog. A 26.4B looped MoE with 1M context, BYOK through Tinker and OpenRouter.
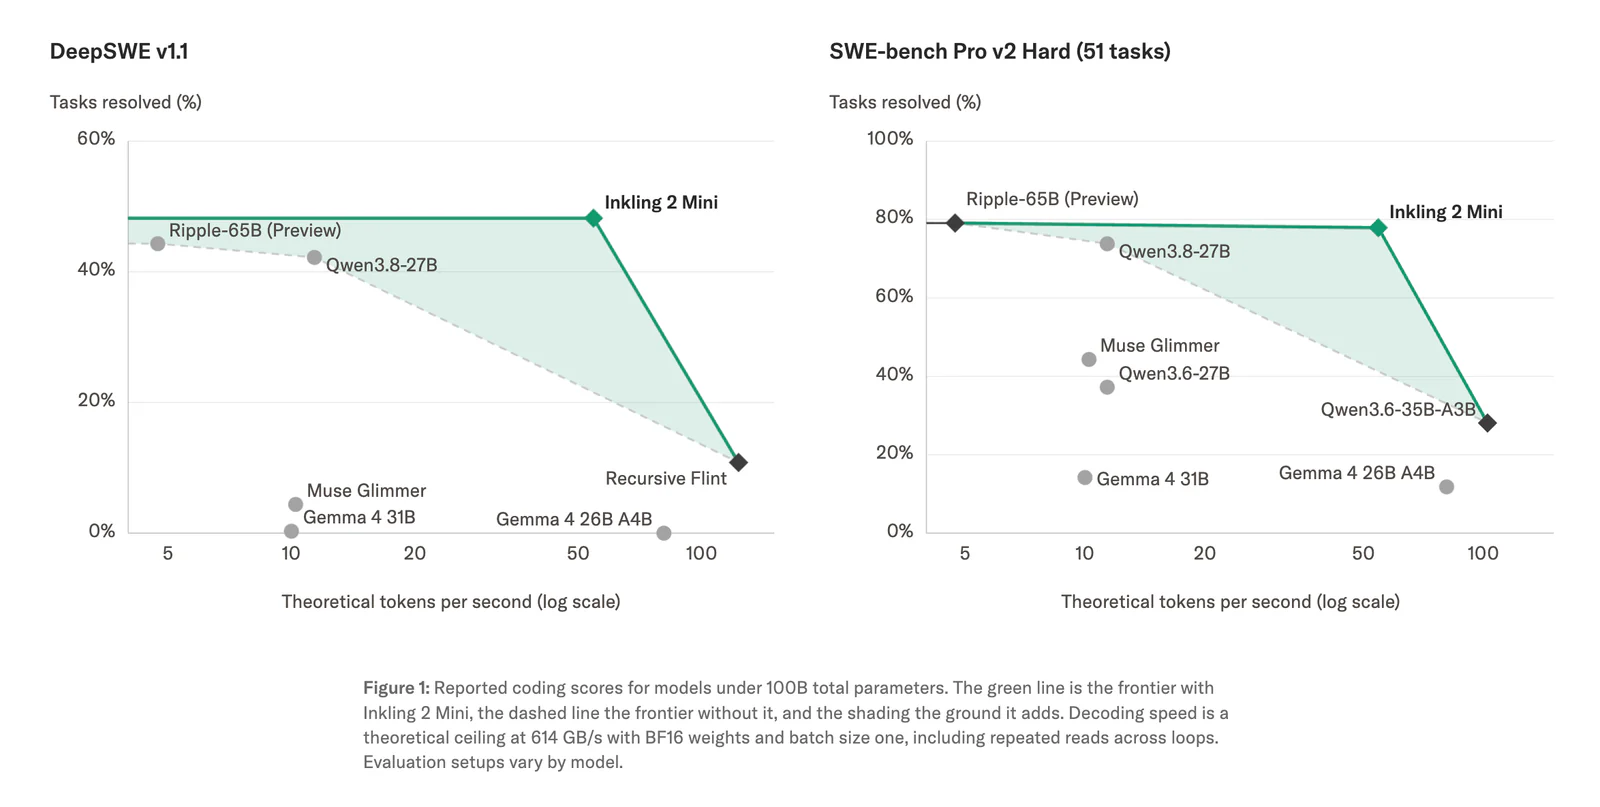
thinkingmachines/inkling-2-mini is Thinking Machines Lab's smallest second-generation model. It is a 26.4B-parameter mixture-of-experts transformer with 3.4B active parameters and a 1M-token context, trained and deployed natively in NVFP4. Its middle layers run three times per token, which the lab calls looping. That gives it more reasoning per token without more parameters. It leads open-weights models under 100B on agentic coding and runs in about 20GB, small enough for a laptop.
It is BYOK-only. Add a Tinker or OpenRouter key under Dashboard → BYOK; the provider bills your own account and AnyRouter charges nothing for the route. Tinker lists it at $0.15 per 1M input and $0.50 per 1M output (256K train / 1M sample wire).
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"

const anyrouter = createAnyRouter()
const { text } = await generateText({
  model: anyrouter("thinkingmachines/inkling-2-mini"),
  prompt: "Summarise what makes a looped transformer different from a normal one.",
})
console.log(text)anyr claude --model "thinkingmachines/inkling-2-mini"Inkling 2 Mini vs open-weight peers
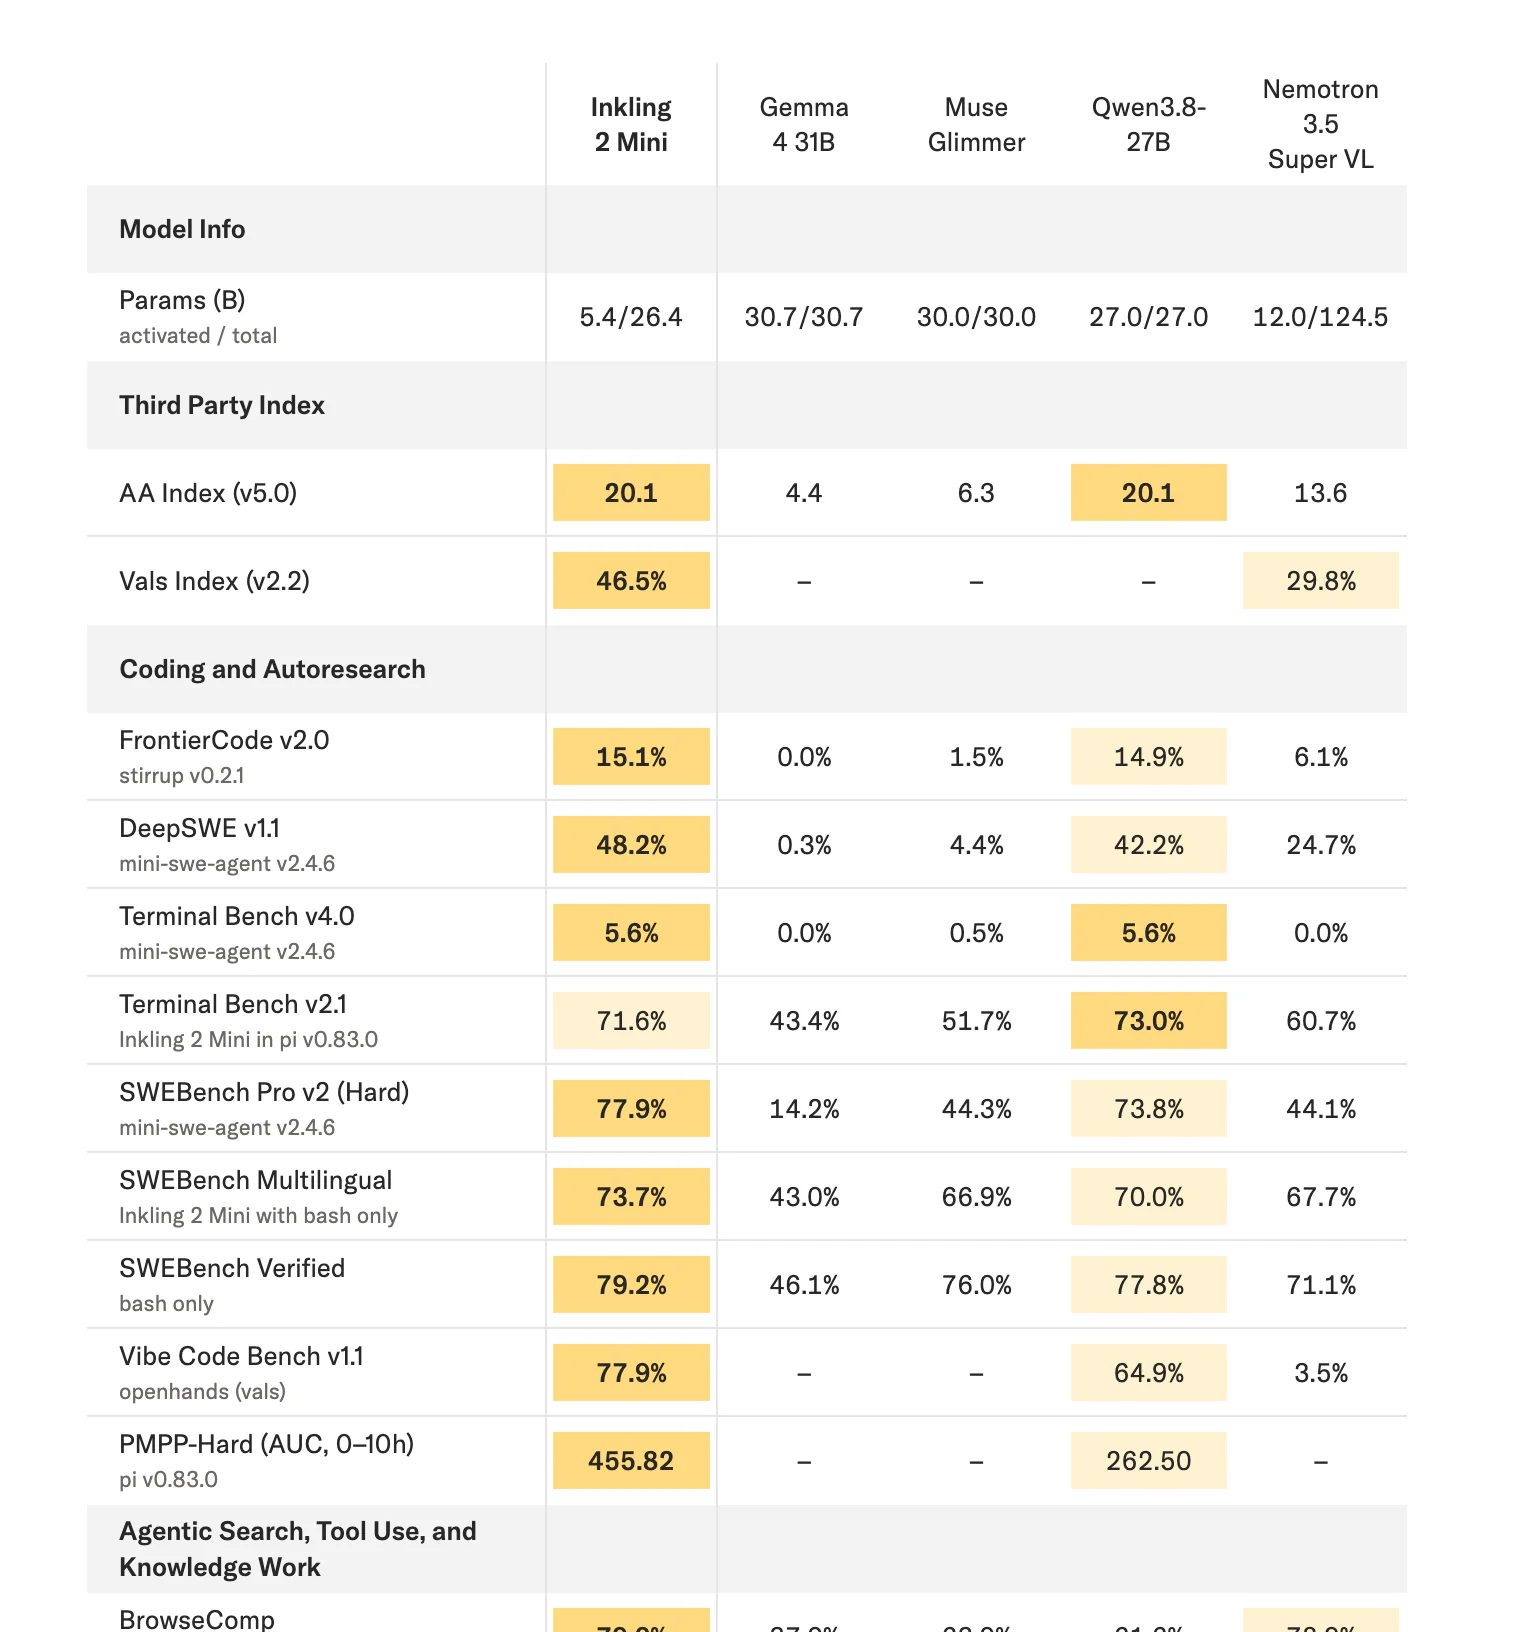
Thinking Machines' Inkling 2 Mini against the four models its launch post compares it with, across coding, agentic search, vision, reasoning and safety, plus the independent evals our catalog holds.
| Vendor benchmarks | Inkling 2 Mini | Gemma 4 31B | Muse Glimmer 30B | Qwen3.8-27B | Nemotron 3.5 Super VL 120B A12B |
|---|---|---|---|---|---|
| Model info | |||||
| Inkling 2 Mini has 3.4B unique active parameters. The vendor's 'activated' column below counts weight activations per token (5.4B), which includes the three loop passes. | |||||
| Params (B)activated per token (incl. loops) / total | 5.4/26.4 | 30.7/30.7 (Highest reported score in this row) | 30.0/30.0 (Second-highest reported score in this row) | 27.0/27.0 | 12.0/124.5 |
| Third party index | |||||
| AA Index (v5.0) | 20.1 (Highest reported score in this row) | 4.4 | 6.3 | 20.1 (Highest reported score in this row) | 13.6 (Second-highest reported score in this row) |
| Vals Index (v2.2) | 46.5% (Highest reported score in this row) | – | – | – | 29.8% (Second-highest reported score in this row) |
| Coding and autoresearch | |||||
| FrontierCode v2.0stirrup v0.2.1 | 15.1% (Highest reported score in this row) | 0.0% | 1.5% | 14.9% (Second-highest reported score in this row) | 6.1% |
| DeepSWE v1.1mini-swe-agent v2.4.6 | 48.2% (Highest reported score in this row) | 0.3% | 4.4% | 42.2% (Second-highest reported score in this row) | 24.7% |
| Terminal Bench v4.0mini-swe-agent v2.4.6 | 5.6% (Highest reported score in this row) | 0.0% | 0.5% (Second-highest reported score in this row) | 5.6% (Highest reported score in this row) | 0.0% |
| Terminal Bench v2.1Inkling 2 Mini in pi v0.83.0 | 71.6% (Second-highest reported score in this row) | 43.4% | 51.7% | 73.0% (Highest reported score in this row) | 60.7% |
| SWEBench Pro v2 (Hard)mini-swe-agent v2.4.6 | 77.9% (Highest reported score in this row) | 14.2% | 44.3% | 73.8% (Second-highest reported score in this row) | 44.1% |
| SWEBench MultilingualInkling 2 Mini with bash only | 73.7% (Highest reported score in this row) | 43.0% | 66.9% | 70.0% (Second-highest reported score in this row) | 67.7% |
| SWEBench Verifiedbash only | 79.2% (Highest reported score in this row) | 46.1% | 76.0% | 77.8% (Second-highest reported score in this row) | 71.1% |
| Vibe Code Bench v1.1openhands (vals) | 77.9% (Highest reported score in this row) | – | – | 64.9% (Second-highest reported score in this row) | 3.5% |
| PMPP-Hard (AUC, 0-10h)pi v0.83.0 | 455.8 (Highest reported score in this row) | – | – | 262.5 (Second-highest reported score in this row) | – |
| Agentic search, tool use and knowledge work | |||||
| BrowseCompInkling 2 Mini with compaction | 79.0% (Highest reported score in this row) | 37.0% | 63.9% | 61.6% | 78.9% (Second-highest reported score in this row) |
| DeepSearchQAInkling 2 Mini with compaction | 85.3% (Highest reported score in this row) | 61.7% | 74.6% | 79.7% (Second-highest reported score in this row) | 77.7% |
| MCP AtlasPublic | 82.7% (Highest reported score in this row) | 54.2% | 75.5% | 77.3% (Second-highest reported score in this row) | 67.7% |
| AA-Briefcase v1.1 | 1263.0 (Second-highest reported score in this row) | 369.0 | 478.0 | 1391.0 (Highest reported score in this row) | 999.0 |
| GDPVal-AA v2.1 | 1319.0 (Second-highest reported score in this row) | 627.0 | 792.0 | 1427.0 (Highest reported score in this row) | 1162.0 |
| JobBench | 49.6% (Highest reported score in this row) | 8.2% | 16.1% | 33.4% | 36.5% (Second-highest reported score in this row) |
| AutomationBench-AA v1.0.6 | 41.8% (Second-highest reported score in this row) | 4.9% | 6.8% | 48.2% (Highest reported score in this row) | 14.8% |
| EnterpriseOps-Gym | 42.0% (Second-highest reported score in this row) | 28.4% | 34.7% | 44.2% (Highest reported score in this row) | 28.1% |
| Vals Finance Index | 50.1% (Highest reported score in this row) | – | – | – | 41.0% (Second-highest reported score in this row) |
| AA-AnalystAgent | 46.3% (Highest reported score in this row) | – | 20.0% (Second-highest reported score in this row) | – | – |
| Diligence Benchbest harness | 48.6% (Highest reported score in this row) | – | 40.9% | 46.4% (Second-highest reported score in this row) | 45.0% |
| Vision interpretation and creation | |||||
| GDP.pdf | 16.8% (Highest reported score in this row) | 6.0% | 11.8% | 16.4% (Second-highest reported score in this row) | 8.0% |
| PerceptionBench | 57.5% (Highest reported score in this row) | 40.7% | 42.8% | 52.4% (Second-highest reported score in this row) | 36.8% |
| MMMU Prostandard 10 | 74.9% (Second-highest reported score in this row) | 73.4% | 74.3% | 76.3% (Highest reported score in this row) | 72.3% |
| OmniDocBench v1.6 | 92.8% (Highest reported score in this row) | 82.5% | 90.4% | 91.5% (Second-highest reported score in this row) | 77.9% |
| ScreenSpot Prooriginal / with Python | 76.5/87.7% (Highest reported score in this row) | 5.9%/– | 75.4%/– (Second-highest reported score in this row) | 57.6/78.9% | 43.5%/– |
| Chartographyoriginal / with Python | 22.1/72.5% (Highest reported score in this row) | 12.0/11.8% | 17.4/25.1% (Second-highest reported score in this row) | 12.2/52.1% | 9.7/29.3% |
| ZeroBench (main)original / with Python | 17.0/34.0% (Highest reported score in this row) | 9.0/12.0% | 9.0/17.0% | 12.0%/– (Second-highest reported score in this row) | 11.0/12.0% |
| MuirBench | 77.5% (Second-highest reported score in this row) | 72.3% | 77.6% (Highest reported score in this row) | 65.9% | 72.7% |
| BVB | 68.4% (Second-highest reported score in this row) | 47.0% | 50.5% | 70.7% (Highest reported score in this row) | 52.1% |
| Reasoning, knowledge and epistemics | |||||
| HLE-Diamond | 15.2% (Second-highest reported score in this row) | 7.2% | 9.1% | 15.3% (Highest reported score in this row) | 8.8% |
| CritPt v2full / hard | 31.4/17.0% (Second-highest reported score in this row) | –/4.0% | –/7.0% | 10.6/4.0% | 36.9/13.5% (Highest reported score in this row) |
| Apex 2025 | 34.4% (Highest reported score in this row) | 5.2% | 4.2% | 18.8% | 22.9% (Second-highest reported score in this row) |
| ARC-AGIv1 / v2 | 84.5/49.3% (Second-highest reported score in this row) | – | – | 87.5/42.4% (Highest reported score in this row) | 22.7/1.5% |
| LongBench v2 | 66.9% (Highest reported score in this row) | 52.9% | 33.1% | 52.3% | 62.1% (Second-highest reported score in this row) |
| GraphWalks BFS256K | 69.7% (Highest reported score in this row) | – | – | 50.4% | 63.3% (Second-highest reported score in this row) |
| MRCR v28-needle 256K-512K | 46.4% (Highest reported score in this row) | – | – | 38.0% (Second-highest reported score in this row) | 5.7% |
| AA-Omniscience v1.1score | -8.6 | -48.5 | -32.2 | -6.4 (Second-highest reported score in this row) | -2.9 (Highest reported score in this row) |
| AA-Omniscience v1.1non-hallucination rate | 63.4% | 14.5% | 16.4% | 71.4% (Highest reported score in this row) | 69.5% (Second-highest reported score in this row) |
| ComplexConstraints v1.1openhands v1.45.0 | 33.4% (Second-highest reported score in this row) | 31.6% | 35.6% (Highest reported score in this row) | 30.1% | 30.1% |
| Safety and alignment | |||||
| FORTRESSadversarial public | 89.5% (Second-highest reported score in this row) | 67.8% | 90.3% (Highest reported score in this row) | 78.8% | 79.6% |
| FORTRESSbenign public | 96.4% | 97.6% (Second-highest reported score in this row) | 89.1% | 97.8% (Highest reported score in this row) | 92.7% |
| StrongREJECTnone | 97.8% | 98.1% | 99.0% (Second-highest reported score in this row) | 99.0% (Second-highest reported score in this row) | 99.4% (Highest reported score in this row) |
| Misbehavior (internal)lower is better | 9.8% (Highest reported score in this row) | 27.6% (Second-highest reported score in this row) | 46.4% | 57.7% | 52.8% |
| Covert misbehavior (internal)lower is better | 8.3% (Highest reported score in this row) | 24.3% (Second-highest reported score in this row) | 45.6% | 33.2% | 43.4% |
| Destructive actions (internal)lower is better | 10.2% (Highest reported score in this row) | 75.8% | 68.8% | 35.2% (Second-highest reported score in this row) | 65.6% |
| Independent evals | Inkling 2 Mini | Gemma 4 31B | Muse Glimmer 30B | Qwen3.8-27B | Nemotron 3.5 Super VL 120B A12B |
|---|---|---|---|---|---|
| GPQA DiamondArtificial Analysis | – | 76.3% | – | – | – |
| ARC-AGI-2Epoch AI | – | – | – | 42.4% | – |
| CursorBench | – | – | – | – | – |
| SciCodeArtificial Analysis, Epoch AI | – | 41.1% (Second-highest reported score in this row) | – | 46.6% (Highest reported score in this row) | – |
| SimpleQA (verified) | – | – | – | – | – |
Sources: Introducing Inkling 2 Mini (Thinking Machines Lab) (vendor-reported, as of 2026-11-21); catalog benchmarks from Artificial Analysis, Epoch AI. A dash means the source reports no value.
Benchmark data from Epoch AI (CC-BY 4.0).
Updated 2026-11-21.
Playbooks: AI SDK, OpenAI SDK, coding agents, playground.
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.