AddedĐã thêm新增
LFM3-VL 2B
Liquid AI's 1.9B vision-language model with video input joins the catalog through your own Infron key.
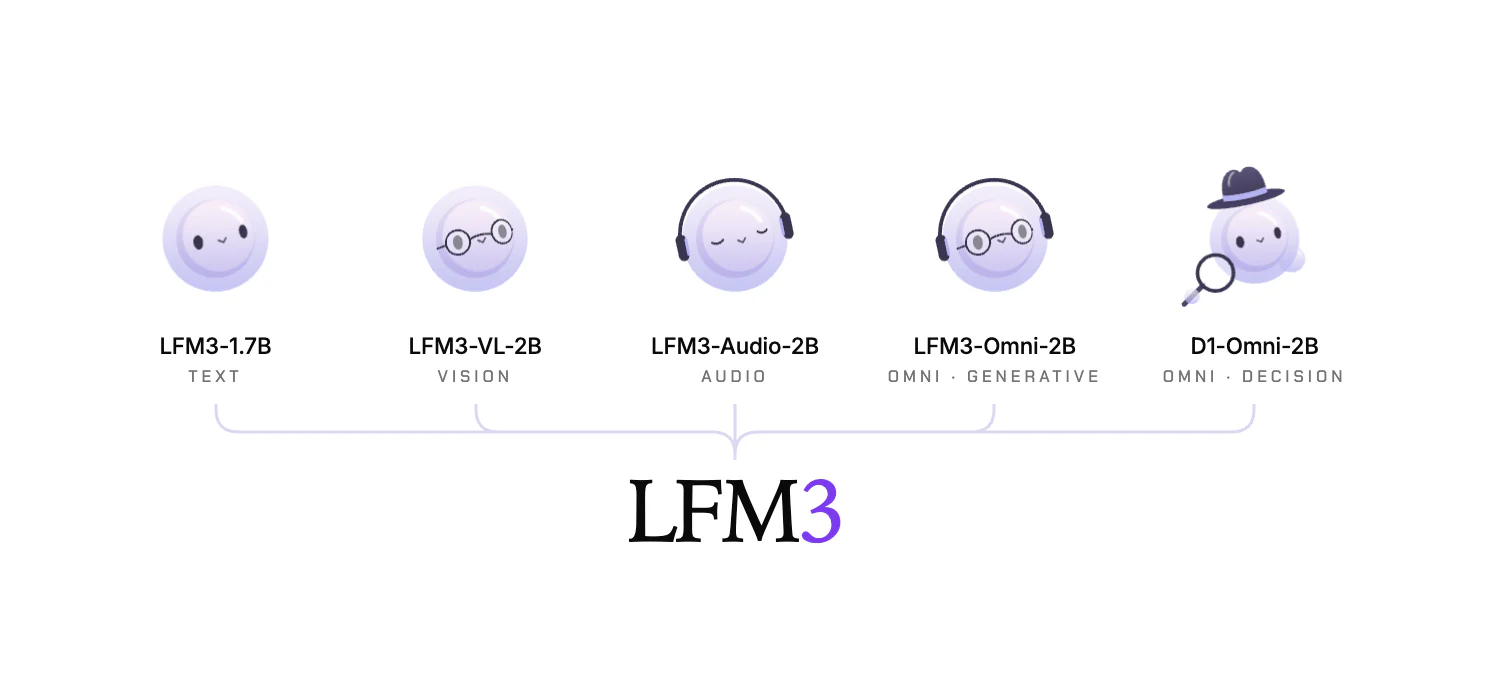
liquid/lfm3-vl-2b is Liquid AI's 1.92B-parameter vision-language model. It takes text, images and video as input (the first LFM vision model to accept video), reasons step by step before it answers, and has a 128K-token context window. Liquid recommends it for questions about video, documents, charts and app screens, not for coding. Reach it through your own Infron key.
AI SDK
import { createAnyRouter } from "@anyr/ai-sdk-provider"
import { generateText } from "ai"
const anyrouter = createAnyRouter()
const { text } = await generateText({ model: anyrouter("liquid/lfm3-vl-2b"), prompt: "Hello" })
Coding agent
curl -fsSL https://anyrouter.dev/cli.sh | bash
anyr login
anyr claude --model "liquid/lfm3-vl-2b"
Playbooks: AI SDK, coding agents, OpenAI SDK.
Looking for the full catalog?Muốn xem toàn bộ danh mục?想看完整目录? Browse all modelsXem tất cả model浏览全部模型.